Qwen 部落格
如何在本地執行 Mistral 3
說明 Mistral 3 是什麼、它是如何建置的、為何你可能想在本機執行它,以及在你的機器或私有伺服器上執行它的三種實用方式——從 Ollama 的「點按即用」便利性,到使用 vLLM/TGI 的生產級 GPU 服務,再到使用 GGUF + llama.cpp 在小型裝置上進行 CPU 推論。
Qwen-image API
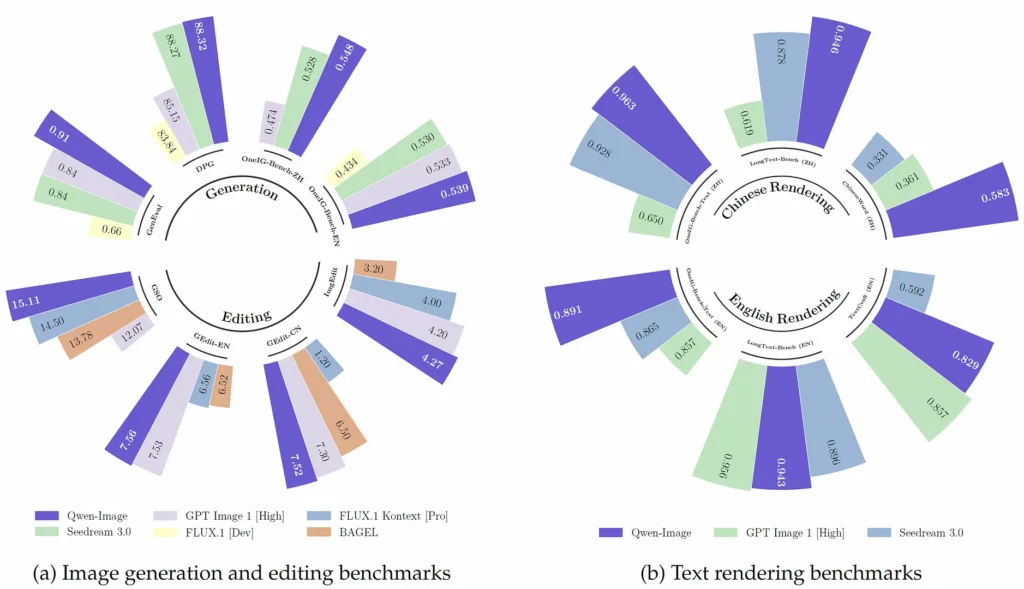
Qwen-Image is an image-generation and image-editing foundation model in the Qwen family designed for high-fidelity text rendering, precise editing, and general text-to-image generation.
Qwen-image-edit API
Qwen-Image-Edit is intended for tasks where editing fidelity matters — e.g., directly changing text on signs, preserving fonts and layout, adding/removing objects while keeping semantic consistency, viewpoint/pose transforms, and fine-grained style transfers.

Alibaba AI Unveils Qwen3-Max: trillion-parameter Qwen model, CometAPI supports
Alibaba’s Qwen team has released Qwen3-Max-Preview (Instruct) — the company’s largest model to date, with more than 1 trillion parameters — and made it
Qwen3-Max-Preview API
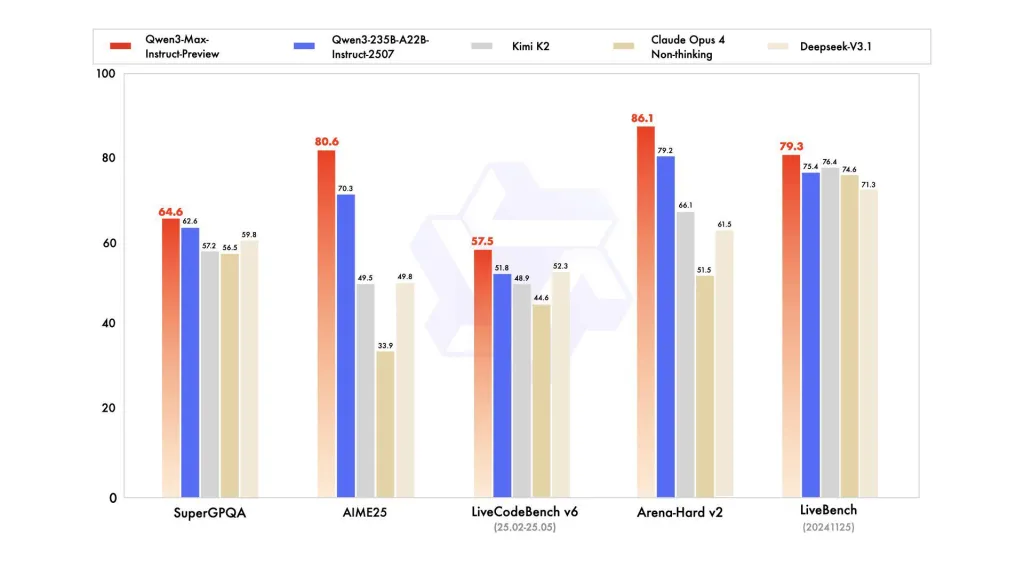
Qwen3-Max-Preview is Alibaba’s latest flagship preview model in the Qwen3 family — a trillion+-parameter, Mixture-of-Experts (MoE) style model with an ultra-long 262k token context window, released in preview for enterprise/cloud use. It targets *deep reasoning, long-document understanding, coding, and agentic workflows.
Which is the best image-editing AI in 2025?
Image-editing AI has moved from fun toy to actual workflow tool in months — not years. If you need to remove backgrounds, swap faces, preserve a character

Is Qwen-Image-Edit the 2025 Breakthrough Image-Editing AI
Alibaba’s Qwen team released Qwen-Image-Edit on August 19, 2025 — an image-editing variant built on the 20B Qwen-Image backbone that promises precise

Can Qwen-Image Model Redefine AI Image Generation and Editing
On August 4, 2025, Alibaba’s Qwen team officially launched Qwen-Image, a 20 billion-parameter multimodal diffusion transformer (MMDiT) foundation model